Quick answer
Upload one photo to Starrd's I'm Just Thayin' template and it makes a 10-second vertical selfie video of you, or your pet, delivering the viral trash-talk monologue straight into the front camera in a sunny parking lot: "I don't care who you are, what weight class you in, where you been… I'm ready to go whenever you are. I'm just sayin'." The head tilts, lean-ins, nods and shaky handheld camera match the original take beat for beat, the mouth moves with every word, and the original audio plays over it. People, dogs, cats and even gorillas work. 100 credits (about $5).
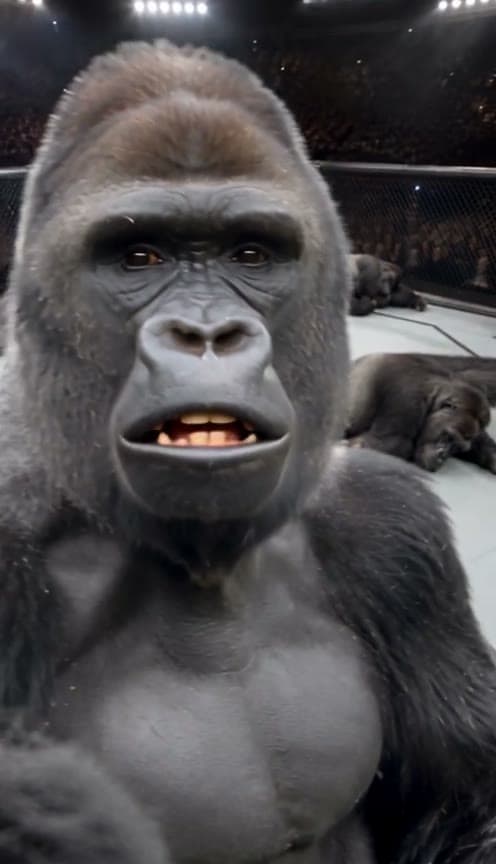
One photo in, and out comes you (or your pet) calling out the whole world from a parking lot: any weight class, any county, ready whenever. I'm just thayin'. Here's one made from a single photo of a silverback:
I'm Just Thayin'
One photo. You or your pet delivering the viral weight-class trash talk to camera. 10 seconds, vertical.
What You Get
- The selfie. A front-camera close-up of you filming yourself at arm's length in a sunny parking lot, a big pickup truck parked behind you.
- The delivery. Every head tilt, lean into the lens, chin lift and slow satisfied nod from the original, on the same beats.
- The mouth. It moves with every word of the line, from "I don't care who you are" to "I'm just sayin'".
- The original audio, uncensored.
- 10 seconds, vertical 9:16, one shaky handheld take, ready for TikTok, Reels and Shorts.
What the Trend Actually Is
The original is a selfie video: a man standing in a near-empty parking lot, phone at arm's length, calmly announcing that he'll fight anyone. Any weight class, anywhere you've been, any county. He's ready whenever you are. He's just saying.
Why it works: the calm. There's no shouting and no build-up, just a flat, total certainty, and the audio became shorthand for calling out a friend, a rival team or the group chat.
Why it suits AI: the line lands harder the less threatening the speaker is. Your mum, your gym buddy, your golden retriever: the more unlikely the challenger, the funnier the challenge.
Pets Welcome
- A real talking jaw. Your pet's own mouth opens and closes with the words, with real teeth and tongue, never cartoon lips.
- The same attitude. Head tilts, lean-ins and the final nod, copied from the original take.
- Still your pet. Its own face, fur and markings the whole time.
Use one clear, well-lit photo where the face is sharp and facing the camera. The parking lot, the truck and the performance come from the template; your photo only decides who's talking.
The Fastest Way
I'm Just Thayin'
One photo, the full 10-second trash talk to camera with the original audio. People and pets.
One photo, 100 credits (about $5), no prompt. The template holds the parking lot, the camera, the delivery and the audio; your photo only decides who's talking. It renders on Seedance 2.5 at 480p, vertical 9:16.
Build It Yourself
1. Turn the clip into a depth map. Run the original selfie video through a depth-estimation model (we used Depth Anything V2) and soften it slightly. You get a greyscale video of shapes, distance and motion only: the head moves and the shaky camera survive, but the original speaker's face doesn't, so it can't leak into your video.
2. Make one still of you in the shot. One selfie-style image of you at arm's length in the parking lot, mouth open mid-sentence.
A photorealistic vertical phone-camera selfie still of the subject from the reference photo, filming themselves at arm's length in a sunny suburban parking lot in the late afternoon. Face and shoulders fill the frame, close to the lens, mid-sentence with the mouth open as if talking straight into the camera, completely sure of themselves. A big dark pickup truck parked right behind them, white painted lines on the asphalt, a low strip-mall building and a pale sky. Wide-angle front-camera look. Keep their exact face and their own clothes. No text, no phone visible in frame.
3. Drive it with the depth map. Feed the still, your original photo and the depth video to a model that copies motion from a reference video (we recommend Seedance 2.5). Tell it the still decides everything you can see and the depth video decides only the movement, the camera and the timing; write the two lines of dialogue in with timestamps so the mouth shapes the words; and say plainly that the result is in full colour, never grey. Lay the original audio back on at the end.
Common Mistakes
Using the raw clip. The original speaker's face comes through into your video. A depth map carries the delivery without it.
Leaving the words out of the prompt. Without the timed dialogue, the mouth just flaps. With it, the mouth shapes the actual words.
Adding a lip-sync pass on animals. Lip-sync tools are trained on human faces. On a dog they do nothing; on a gorilla they smear the mouth. The video model's own mouth movement is cleaner.
FAQ
How many photos? One.
Does it work with my pet? Yes. Its own jaw moves with the words, with real teeth and tongue.
How long is it? 10 seconds, vertical 9:16.
What does it cost? 100 credits, about $5.
Related Reading
- How to Make the 'Yo Dookie! Wazzup' AI Video: another meme you can drop yourself into
- How to Make the 'Hit The Road Dude' AI Video: the other viral self-insert
- How to Make the 'Hold On, I'm On the Phone' Pet AI Video: talking pets
- Viral AI Video Trends 2026: every self-insert trend in one place