Quick answer
Starrd's Choosin' Texas Remix Emo Version template recreates @kobbapot's viral emo cover of "Choosin' Texas" from one photo. You, or your pet, perform the whole 30-second one-take routine straight to a phone camera: the pointing kick, leaning back on a ledge and bouncing, squats, rock-and-roll horns and screamed notes, crossed arms, and the final drop to one knee, lip-synced to the original audio. It happens in the place from your photo, and you keep exactly the look your photo shows. The original's cowboy hat isn't added. Vertical 9:16, Seedance 2.5, 250 credits (about $12.50).
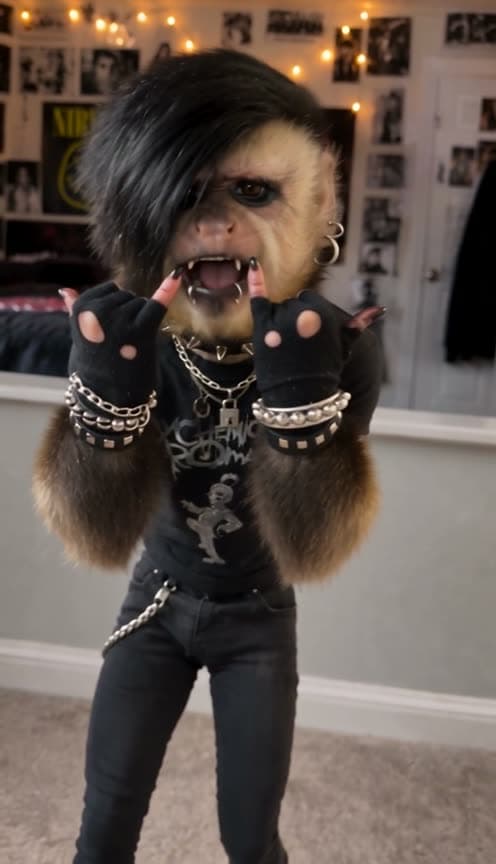
One photo in, and out comes you, or your pet, belting the viral emo remix of "Choosin' Texas" straight to the camera: bouncing on the ledge, rock horns up, screaming the notes and dropping to one knee. All 30 seconds, one take, lip-synced. Here it is with an emo monkey:
Choosin' Texas Remix Emo Version
One photo. You or your pet belt the viral emo 'Choosin' Texas' remix: ledge bounces, rock horns, screamed notes and the drop to one knee.
What You Get
- The whole performance. All 30 seconds of the one-take routine, every move on the original's timing.
- Real lip sync. Your mouth follows the original vocal, wide open on the screamed notes.
- The moves. The pointing kick, leaning back on the ledge and bouncing, the squats, the rock horns, the crossed arms and the drop to one knee.
- Your own look and place. Exactly what your photo shows, in the place from your photo. No cowboy hat unless you ask for one.
- People or pets. Pets stand up and perform it as real animals, with paws instead of hands.
- 30 seconds, vertical 9:16, ready for TikTok, Reels and Shorts.
What the Trend Actually Is
@kobbapot posted it on September 29, 2026, tagging Ella Langley, and it passed 13 million plays and 1.6 million likes. In a black cowboy hat, a fitted black tee and boots, on a parking-garage roof at night with the city lights behind him, he gives "Choosin' Texas" the full emo treatment: pained brows, rock horns, screamed notes and total commitment, all in one handheld take.
Why it suits AI: the joke is the commitment. One photo lets you, your friend or your dog give the same all-in performance without learning the routine.
The Routine, Beat by Beat
| Time | Move |
|---|---|
| 0:00 | A dramatic opening pose: one arm pointing at the sky, one leg kicked out |
| 1.3s | Steps to the camera and starts singing |
| 3s | Leans back on the ledge, gripping it, bouncing |
| 8.5s | A deep squat-bounce |
| 10s | Rock horns up by the face, screaming into the camera |
| 13s | Half sideways, hands clasped and pleading |
| 16s | Back on the ledge, bouncing, head thrown back |
| 21s | Arms crossed in an X, then a hand to the chest |
| 24s | Lunges at the camera and swings down low |
| 26s | Drops to one knee, singing to the floor |
Your Look, Your Place
- Your own face, hair and clothes. Pajamas stay pajamas; nobody gets the original's black outfit or boots.
- No cowboy hat. You're bare-headed unless your photo has a hat, or you ask for one in the Director's Notes.
- Your own place. The routine happens where your photo was taken, with a counter, the back of a sofa or a low wall as the ledge.
Use a full-body photo if you can: the routine is full-body, so the clothes and shoes in the photo are what you'll perform in. If someone else, or a pet, is at the edge of your photo, that's fine: only the main subject performs.
The Fastest Way
Choosin' Texas Remix Emo Version
One photo, the full 30-second emo performance with the original audio, lip-synced.
One photo, 250 credits (about $12.50), no prompt. It renders on Seedance 2.5 at 480p, vertical 9:16.
Build It Yourself
1. Take the hat off the original. A cowboy hat's brim is a huge shape, and a depth map would hand it to everyone. Find the hat in every frame with a text-prompted segmentation model, stop the mask at the eyebrows so the face is untouched, inpaint it from the background and draw a plain rounded head in its place.
2. Paint out the caption and the bad first frames. The burned-in "Emo choosin Texas remix" label would show up as raised letters, and the clip opens with a split second of the camera pointing at the floor.
3. Turn it into a depth map with the vocal inside. Run Depth Anything V2 on the cleaned frames. It's one handheld take that swings from standing to kneeling, so set the contrast from a rolling two-second window rather than one curve for the whole clip. Then put the original audio inside the depth video.
4. Make a character sheet from the photo. A large opening frame of the subject full-body in the photo's own place, standing in front of a waist-high ledge, plus a full-body panel and a singing close-up.
A candid vertical phone-video still of the person in Image 1, full body from head to feet, facing the camera, standing just in front of a waist-high ledge that runs straight across the frame behind them, in the same place as Image 1, with the same setting, light and time of day, extended to fill a tall frame. No text.
5. Drive it. Feed the sheet, the photo and the depth video to a model that copies motion from a reference video (we recommend Seedance 2.5). Write a beat list for the signature moves, and say that the round head shape is a bare head. Then lay the original audio back on at the end.
Common Mistakes
Leaving the hat in the depth map. Everyone comes out in a cowboy hat, whatever their photo shows.
Forgetting what was under the hat. The original has long locs under the brim, and their outline gives short-haired people a mullet. Lock the hair to the length in the photo.
One contrast curve for the whole take. The kneel at the end points the camera at the floor and flattens the subject. Use a rolling window.
"The animal is the subject" rules. If the photo is a person with a dog at their feet, the dog gets cast. Pick the largest, most central subject instead.
FAQ
How many photos? One.
Pets? Yes, as real animals with paws.
How long is it? 30 seconds, vertical 9:16.
What does it cost? 250 credits, about $12.50.
Related Reading
- How to Make the 'Deep Down In My Heart… I Still Love You' AI Crying Meme: another viral clip recast with your face, lip-synced
- How to Make the 'Hit the Road Dude' AI Video: another viral clip, lip-synced line for line
- How to Make the 'How I Become a Millionaire' AI Video: the ChatGPT voice-memo skit, starring you or your pet
- Viral AI Video Trends 2026: every trend we've turned into a template this year